Versioned JSON contracts
Pipelines are declarative JSON: schema_version, nodes, depends_on, parameters, settings. Every update creates a new immutable integer version, and the contract is additive-only.
Run it, then build on it
Eight steps, each executed on a fresh checkout before it was written here. Start the server with sample data. Create your key on the Keys page. Connect Claude Code, Cursor or Copilot over MCP. Let the agent author and run a pipeline, release it, publish it as an API, bind a key to that API, and call it. Every command, config block and response below is copied from that run.
Step 1
You need Docker with the compose plugin and a checkout of the repository. Nothing else. The build runs inside a throwaway JDK container, so there is no local Java to install. One command:
./app.sh --start --demo nyc,trade,lake
What you see. The first build is the slow one because the dependency cache is cold. Later starts reuse it. When the stack is healthy the script prints the address and the login it seeded:
==> UP — http://localhost:8080
==> LOGIN: admin@local.test / <a generated one-time password>
    The one-time credential from deploy/secrets.env is still pending — the app will make
    you set a new password at first sign-in (auth.md §5A.4).
==> demo data loaded (nyc,trade,lake). The example pipelines are seeded into the
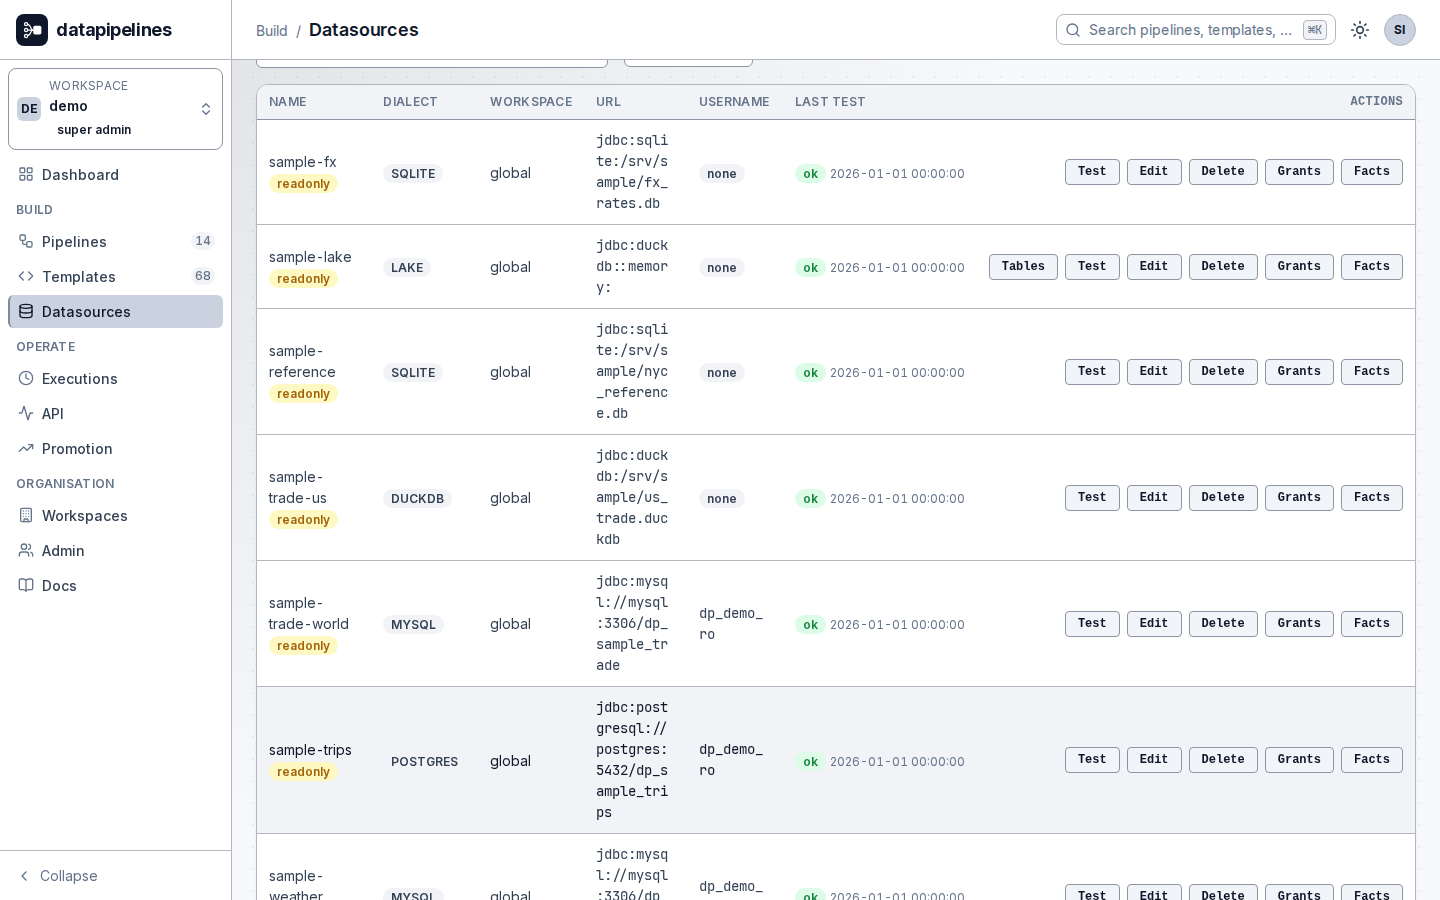
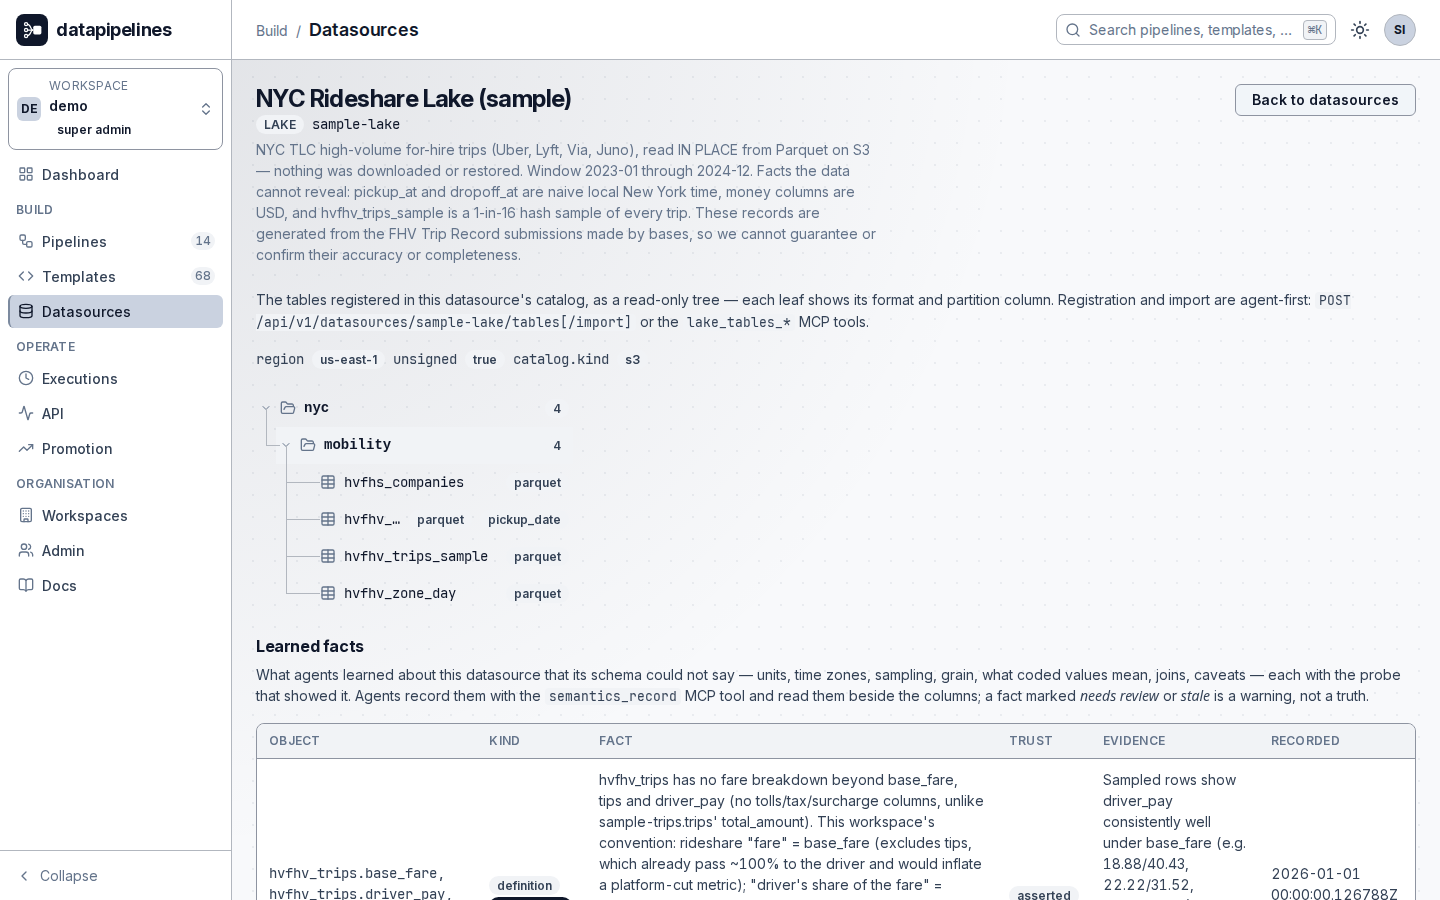
shipped 'demo' workspace — the one every login lands in (auth.md §4.2 step 4).What just happened. The script started Postgres, Redis, the app and the demo loaders, ran the migrations and seeded the first admin behind a one-time password. The --demo flag restored three published sample families and registered them as read-only datasources with example pipelines beside them: NYC taxi trips on Postgres, NOAA weather on MySQL, the zone reference on SQLite, US trade at HS-6 grain on DuckDB, and a rideshare lake read in place as Parquet and Iceberg on S3.
Now open http://localhost:8080 and sign in with the printed login. The app forces a password change of twelve characters or more before anything else, then lands on the dashboard. You are already inside the demo workspace, which is where the example pipelines live.
Step 2
What you do. No key exists until someone creates one. Open the Keys page, choose New API key, pick the kind mcp, and give it a role: the dialog offers exactly the roles whose permissions are a subset of yours. Create shows the full key once; copy it into the client config in step 3 and keep the page's row for revoking later.
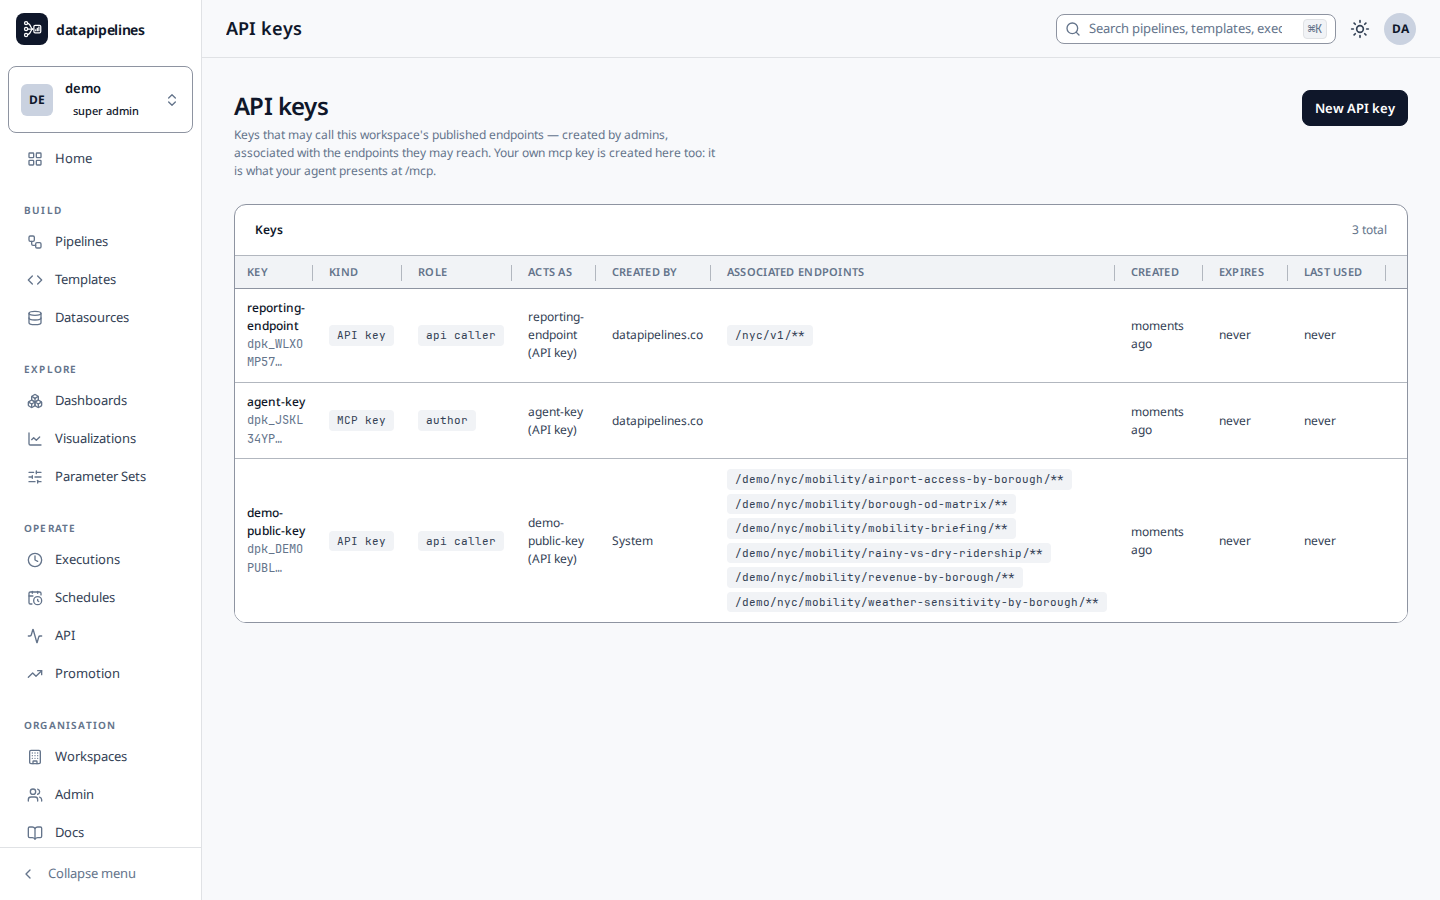
What you see. The key acts as its own identity holding the role you gave it. An author-role key can create and run; a promoter-role key reads and promotes. For the demo workspace a workspace admin can offer any of the three roles, and an author exactly one: their own. The subset rule decides, never a promise.
What just happened. The key was created on the Keys page and pinned to the workspace you are in, demo here, with an identity of its own. It is shown exactly once, and the server keeps only the hash, so paste it into the client config now. Deleting the key on the same page revokes it; removing the member who created a key revokes it too. Administration stays with signed-in people; no key can hold it.
Step 3
/mcpWhat you do. Every client needs the same two facts: the endpoint POST http://localhost:8080/mcp and the key from step 2 in the DP-API-Key header. The blocks below are the ones the setup page shows. They are one shared fragment, so the two pages cannot drift.
claude mcp add --transport http datapipelines http://localhost:8080/mcp \
--header "DP-API-Key: dpk_<id>.<secret>"~/.cursor/mcp.json{
"mcpServers": {
"datapipelines": {
"url": "http://localhost:8080/mcp",
"headers": { "DP-API-Key": "dpk_<id>.<secret>" }
}
}
}.vscode/mcp.json{
"servers": {
"datapipelines": {
"type": "http",
"url": "http://localhost:8080/mcp",
"headers": { "DP-API-Key": "dpk_<id>.<secret>" }
}
}
}{
"mcpServers": {
"datapipelines": {
"url": "http://localhost:8080/mcp",
"headers": { "Authorization": "Bearer dpk_<id>.<secret>" }
}
}
}What you see, from Claude Code on the run this page was written from:
$ claude mcp list
…
datapipelines: http://localhost:8080/mcp (HTTP) - ✔ ConnectedWhat just happened. The client ran the MCP initialize handshake against /mcp with the key, and the server answered with its capabilities and its working instructions: the authoring flow, the naming rules, and what it may not do. The endpoint accepts API keys only; a browser session is refused, deliberately. Exactly 61 tools cover the full lifecycle, starting with pipelines_list and datasources_list.
Step 4
What you do. Ask a question in plain language. This is the prompt the run used, verbatim:
List the datasources and their schemas to find the NYC taxi trips and the daily
weather. Author a NEW pipeline under the test/ folder that answers: total fare
revenue per NYC borough, split by rainy vs dry days. It must join the trips data
with the weather data. Execute it and read the result rows. Do not release
anything. Stop after reporting.What you see. The agent works the server's own authoring flow, in this order. The calls below are from the run's transcript:
pipelines_list and datasources_list: the existing folders and the demo datasources.datasources_get_schemas → get_tables → get_columns: the real columns, read, never recalled.sql_probe: candidate SQL against each source, before anything exists.templates_create and templates_render: the SQL previewed before a pipeline references it.pipelines_create: test/borough_fare_by_weather, a versioned JSON DAG of SQL nodes.pipelines_execute → executions_get_result: SUCCESS, 12 rows in under four seconds.pipelines_run_checks: the release checks pass.The first rows of the answer, on 2024 defaults. The est ×16 column scales the 1-in-16 sample to the population:
| Borough | Weather | Days | Trips | Fare, sampled | Fare, est ×16 |
|---|---|---|---|---|---|
| Manhattan | dry | 290 | 1,741,947 | $28,048,896.60 | $448,782,345.60 |
| Manhattan | rainy | 76 | 462,115 | $7,465,129.64 | $119,442,074.24 |
| Brooklyn | dry | 290 | 27,697 | $776,411.11 | $12,422,577.76 |
| Brooklyn | rainy | 76 | 7,171 | $200,777.83 | $3,212,445.28 |
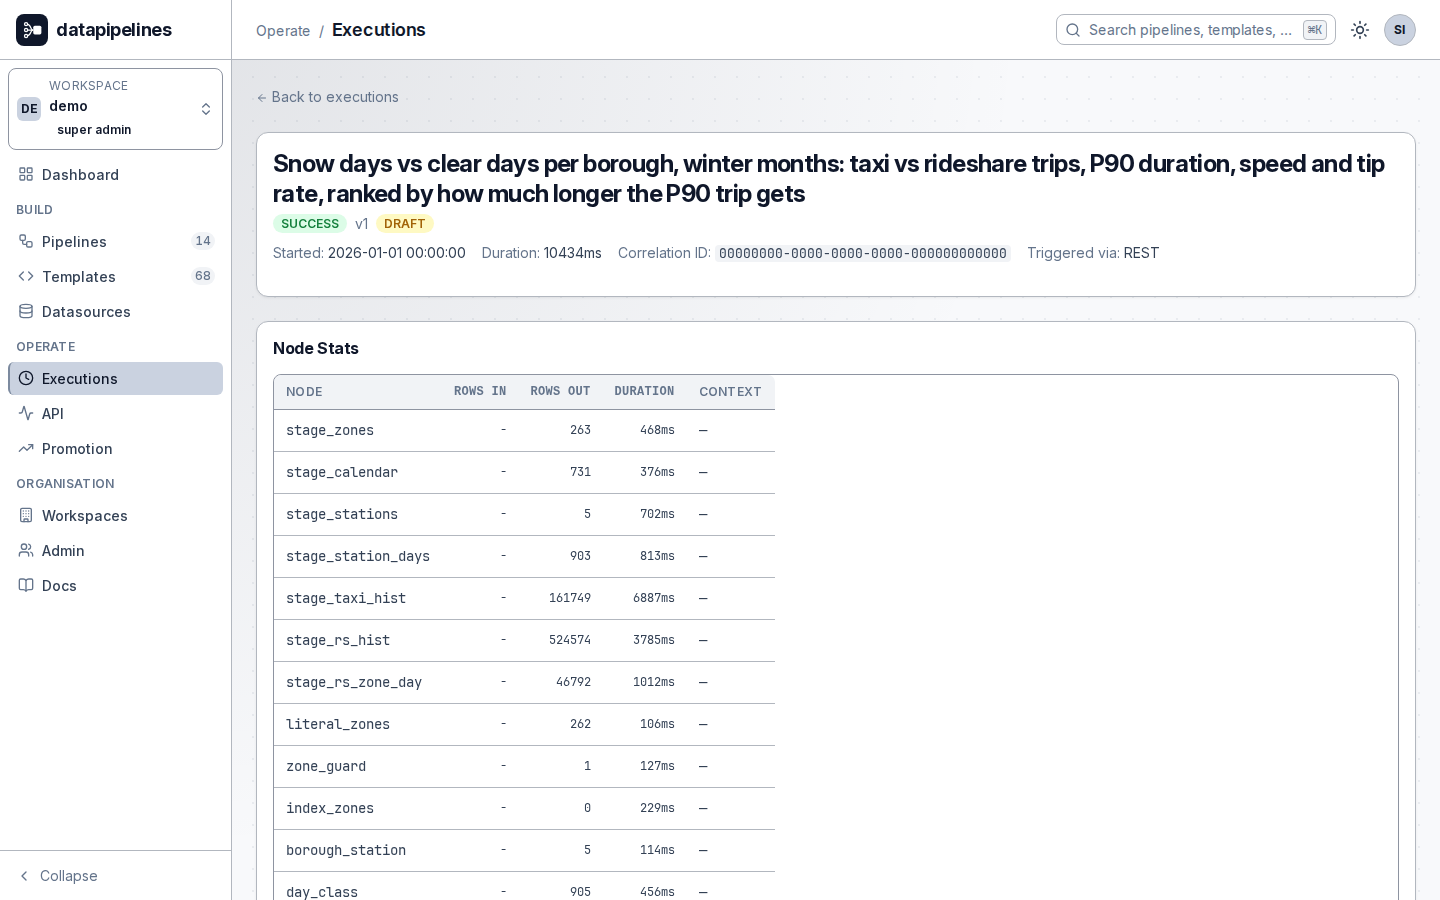
What just happened. Each node read its own engine: trips from Postgres, rainfall from MySQL, the borough lookup from SQLite. The federated join happened in a per-run in-memory staging database that exists only for the execution. Nothing was copied into a warehouse first. And the agent stopped at draft, because no MCP tool can release anything. That is a design rule, not a demo limitation.
Step 5
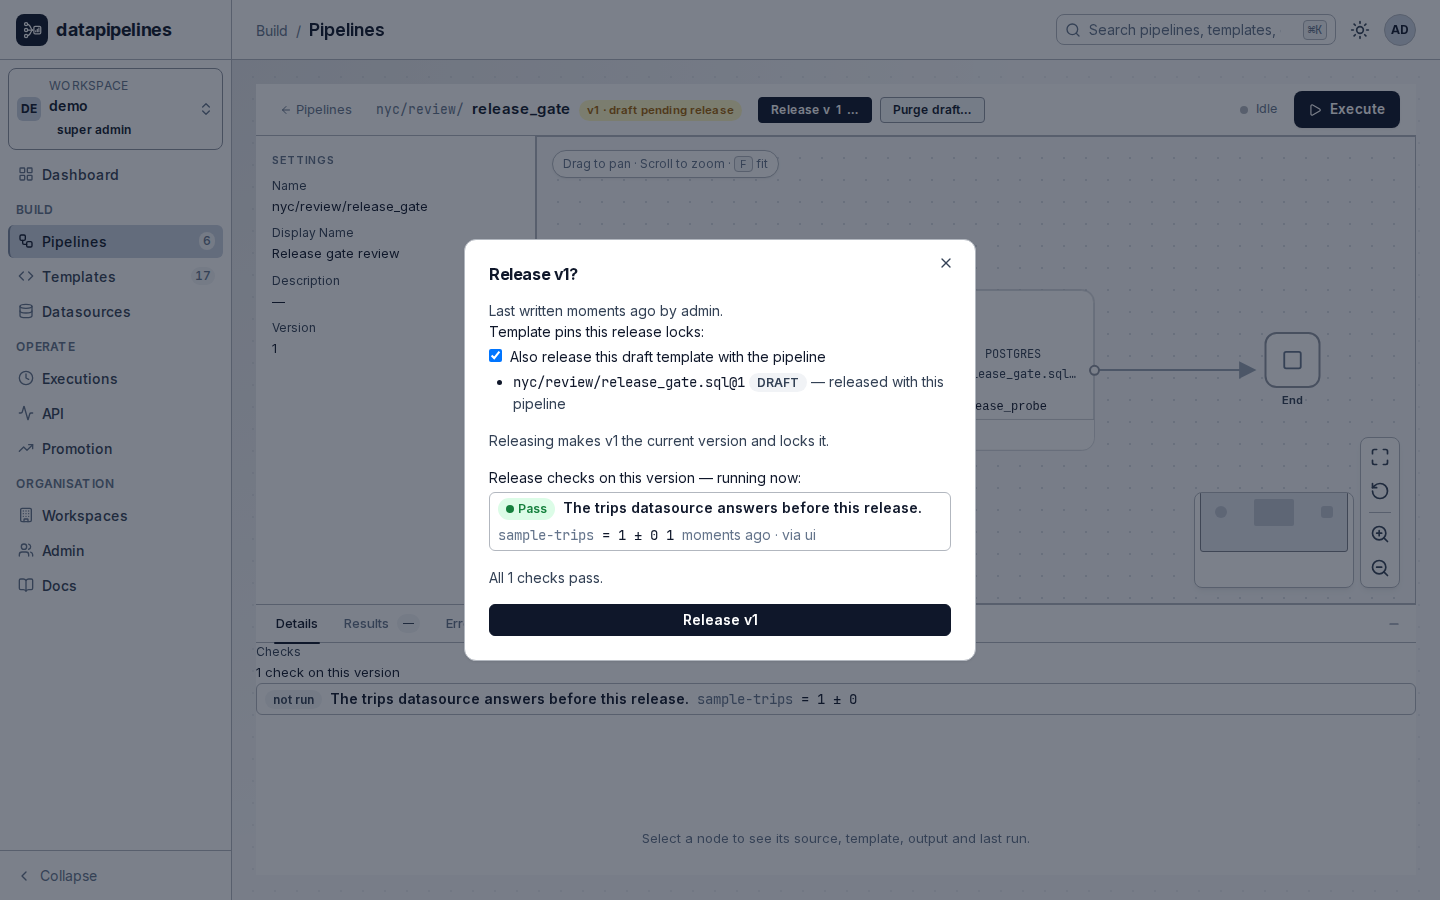
What you do. Open the pipeline in the editor and choose Release v1…. This is the step the agent cannot do for you. Release needs the promote role, which the bootstrap admin from step 1 holds, and there is deliberately no MCP tool for it.
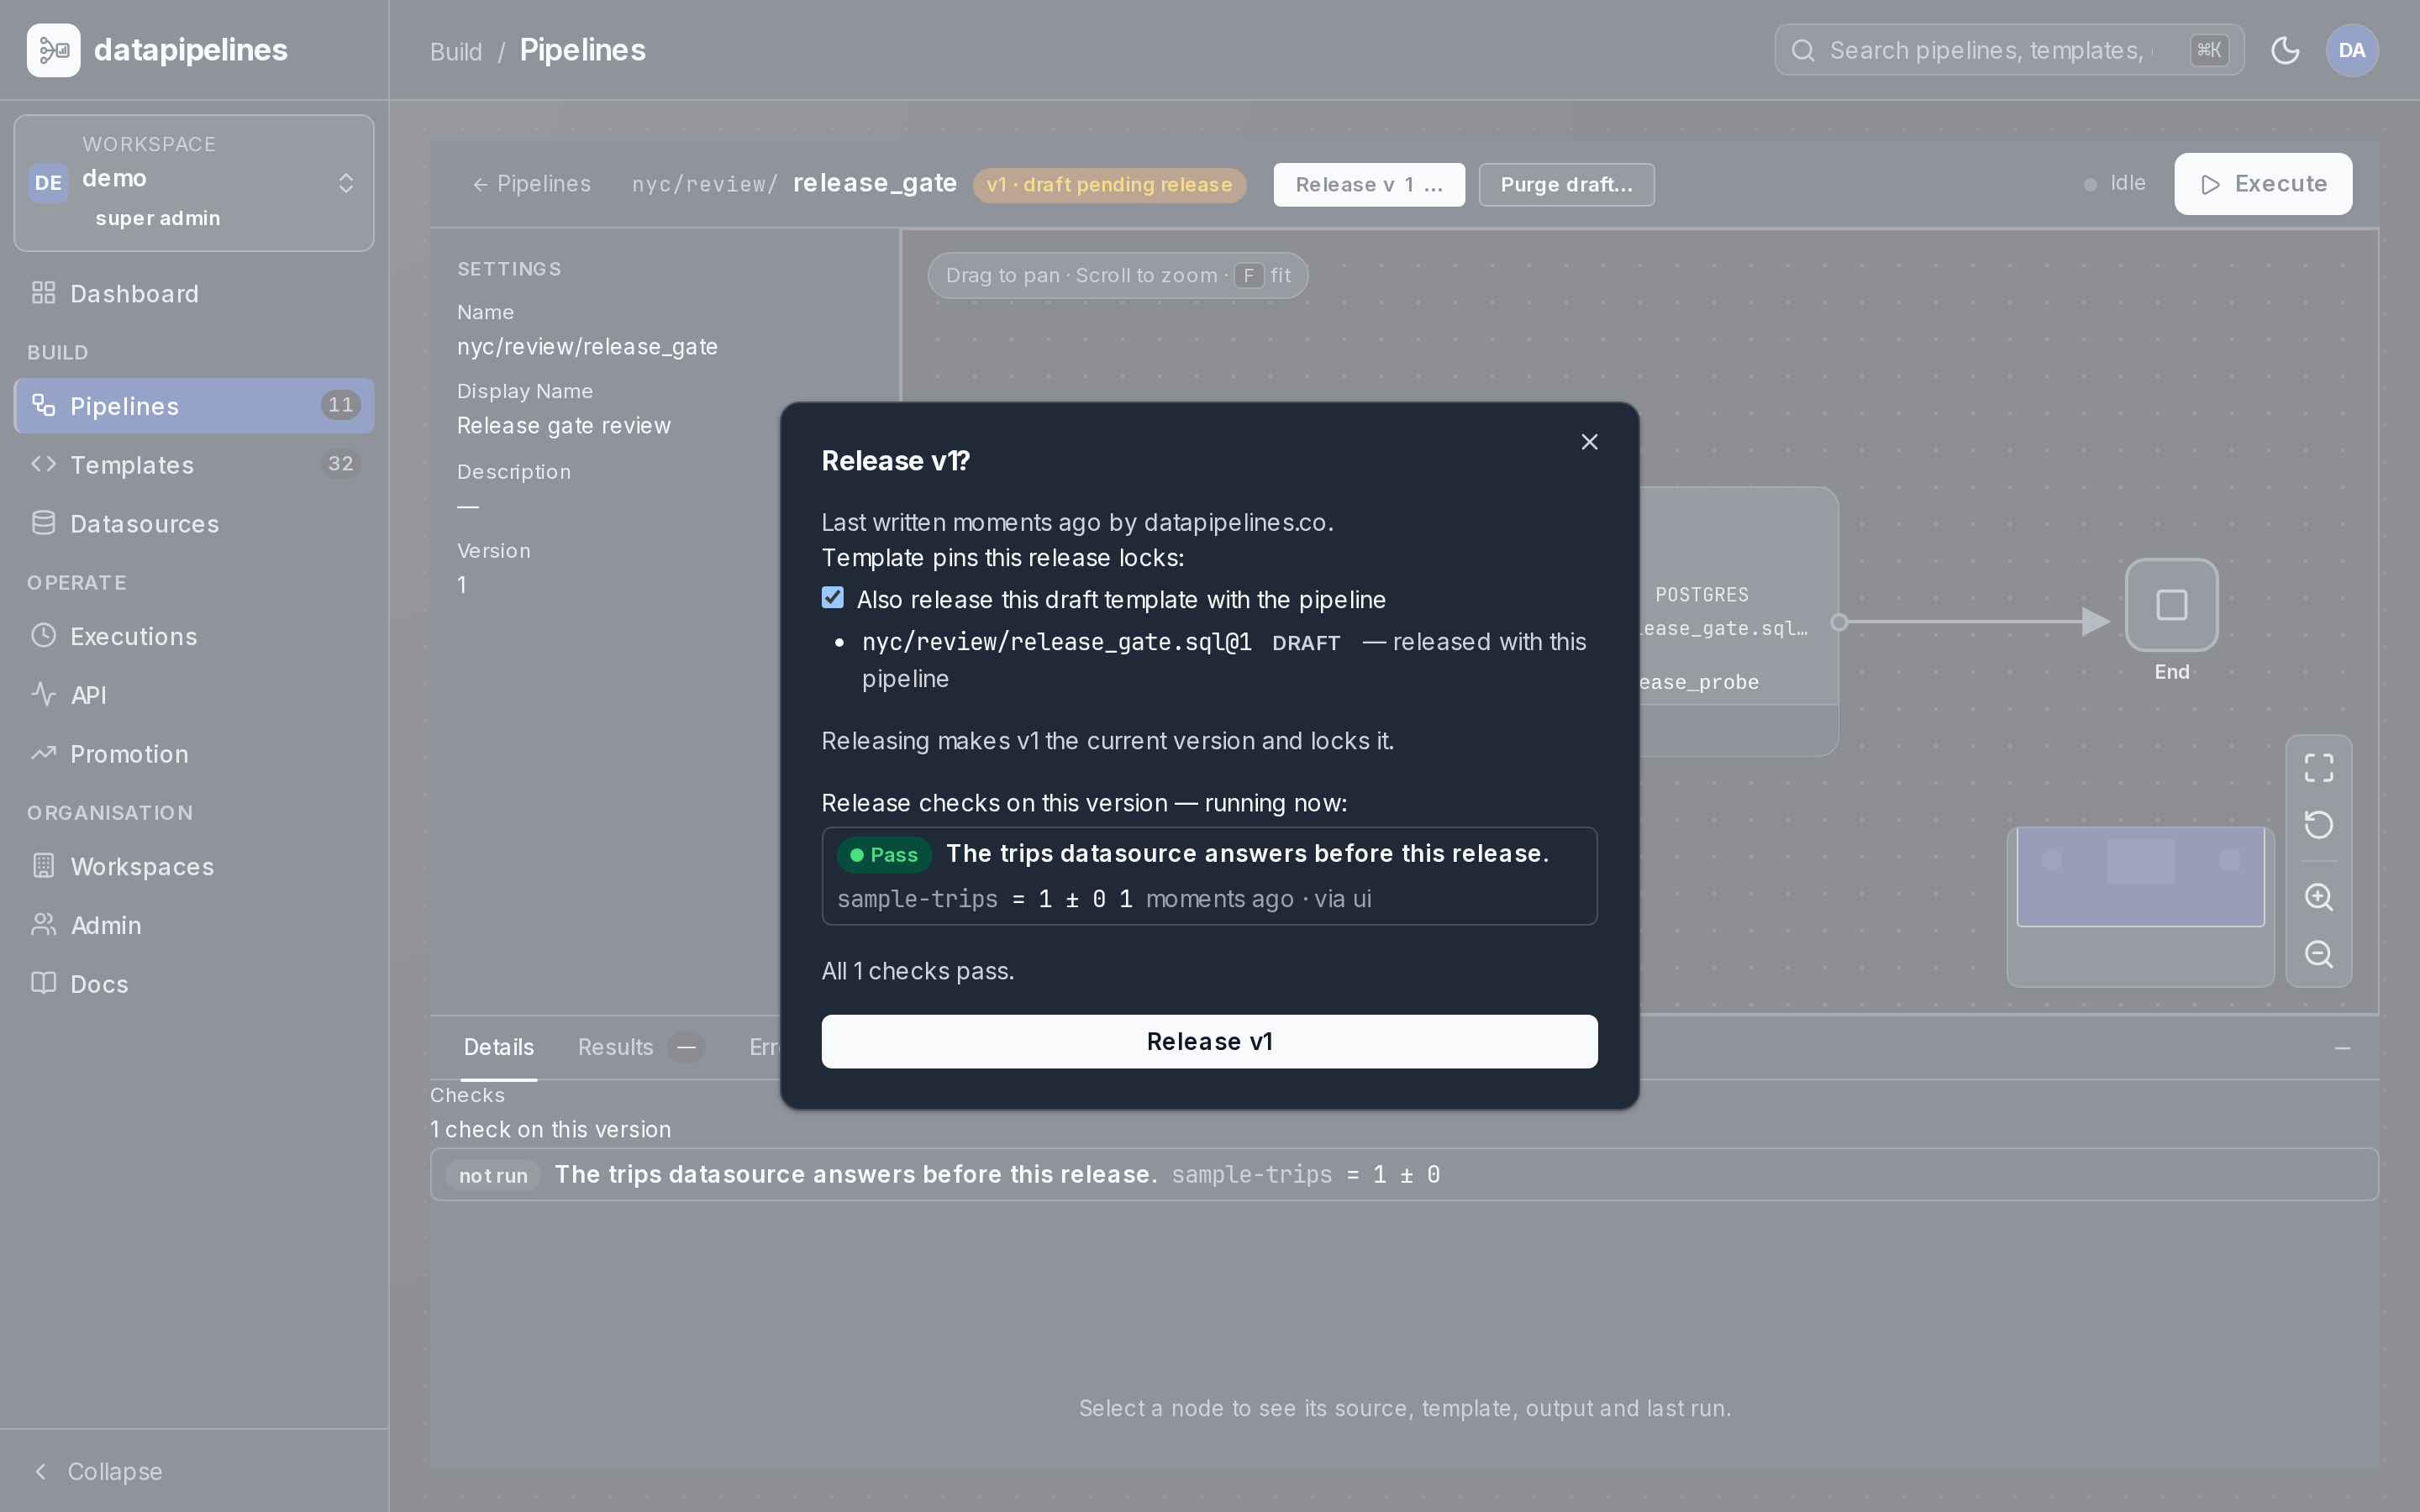
What you see. The dialog runs the pipeline's release checks as it opens and answers every template pin before it offers the button. The two draft templates the agent created ride along through the checked consent. One click, and the response flips the pipeline to RELEASED.
What just happened. Version 1 became immutable. Everything that serves the pipeline now runs the released logic: the executions, and the endpoint you are about to publish. A further change is a new draft that changes nothing live. The same release exists as POST /api/v1/pipelines/{id}/release.
Step 6
What you do. Ask the agent to publish the pipeline under a path. It calls the endpoints_create MCP tool with the path and the pipeline's name:
endpoints_create {"path": "/nyc/v1/borough-fare-by-weather",
                  "pipeline": "test/borough_fare_by_weather",
"description": "Fare revenue per borough, rainy vs dry days"}What you see. The tool answers with the URL the path grammar built:
{"path": "/nyc/v1/borough-fare-by-weather",
 "pipeline": "test/borough_fare_by_weather",
 "timeout_seconds": 30, "enabled": true,
"url": "/api/nyc/v1/borough-fare-by-weather", …}What just happened. Publication is refused unless the pipeline has a released version and is side-effect-free. Every node reads, and writes at most to the per-run tempdb or to the caller. That is what makes a GET safe to retry, preload or crawl. The path is category, version, path, and a category like v1 or the literal api can never be published, so a published path can never shadow a product route. The same publish exists as POST /api/v1/endpoints for a signed-in session. Your MCP key reaches /mcp and nothing else, so a script publishes with a session, not with that key. The API section in the UI lists the endpoint.
Step 7
What you do. An admin creates an API key on the API keys page at /api-keys and associates it with the endpoint's path. In the demo you are the admin, so this is you. Choose New API key and keep the kind API key, which is the endpoint kind on the wire. Name it weather-app, tick the endpoint's path under Associated endpoints, and choose Create key. The key is shown once. Copy it for step 8.
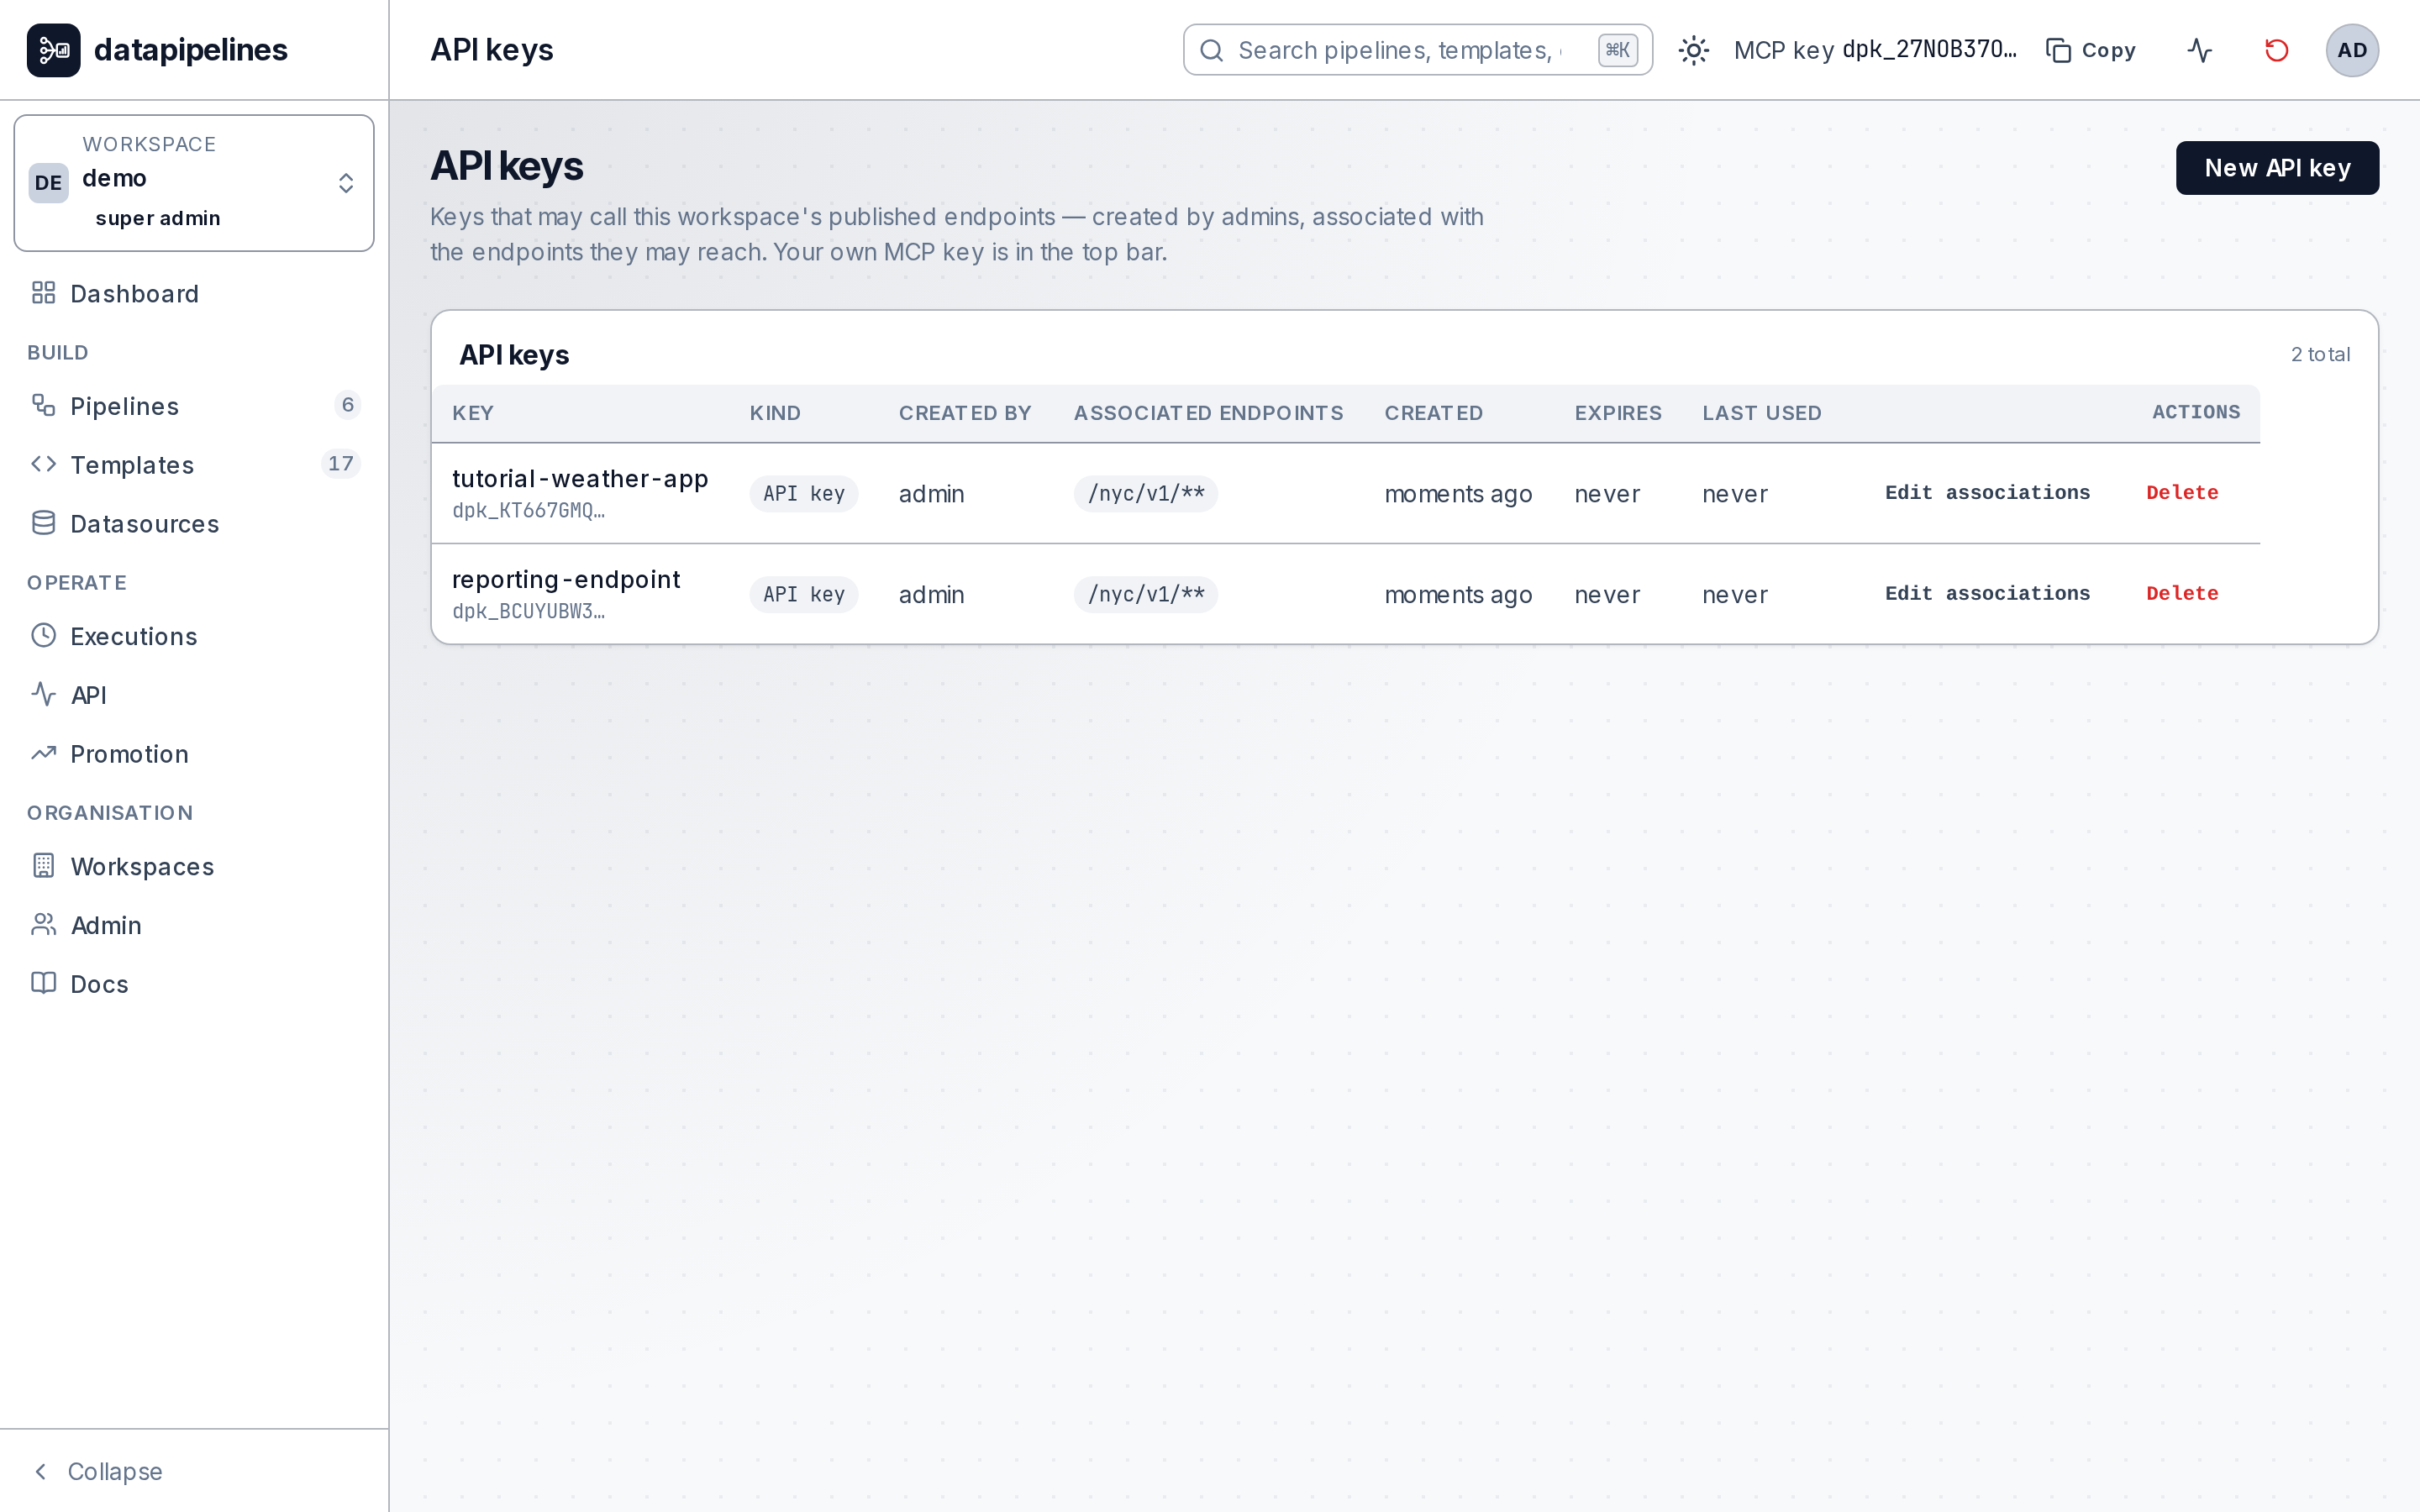
What just happened. The key acts as its own identity with one fixed role, api caller. The keys table's Acts as column names that identity after the key. Its reach is exactly its bindings, and the nearest bound ancestor decides: a binding to /nyc would cover every endpoint under it. The negative control, from the same run: the agent's key from step 2 is refused here, because an MCP key reaches /mcp and nothing else:
$ curl http://localhost:8080/api/nyc/v1/borough-fare-by-weather \
    -H "DP-API-Key: dpk_<the agent key>"
403 — {"error": {"code": "endpoint.key_kind_refused",
"details": {"reason": "user_key_off_surface"}, …}}Step 8
What you do. A GET with the API key from step 7. No session, no SDK:
curl http://localhost:8080/api/nyc/v1/borough-fare-by-weather \
-H "DP-API-Key: dpk_<id>.<secret>"What you see. 200, and the first page with its cursor. The output below is trimmed; the run returned 12 rows:
{
  "execution_id": "be1f1c32-f13c-4540-be4c-c9aee8e95fb0",
  "schema": [{"name": "borough", "type": "STRING", "nullable": true}, …],
  "rows": [["Bronx", "dry", "290", "5718", "185793.34", "2972693.44"], …],
  "row_count": 12, "total_rows": 12, "has_more": false,
  "result_url": "http://localhost:8080/api/v1/executions/be1f1c32-…/result",
  "ttl_seconds": 300
}What just happened. The endpoint executed the latest released version in-process, audited against the key, and materialized the full result before answering. DP-Result-Page-Rows: 5 returns five rows with has_more: true, and the cursor pages the rest inside the TTL with GET …/result?offset=5&limit=5. The pipeline's declared parameters arrive as the query string, like ?year=2023. Validation is strict on purpose: a typo like ?yr=2023 is a 400 listing every accepted parameter, because a silently defaulted year would return plausible, wrong rows. A run that outlives the endpoint's timeout answers 202 with the cursor instead of an error. The answer is coming.
Inside the application
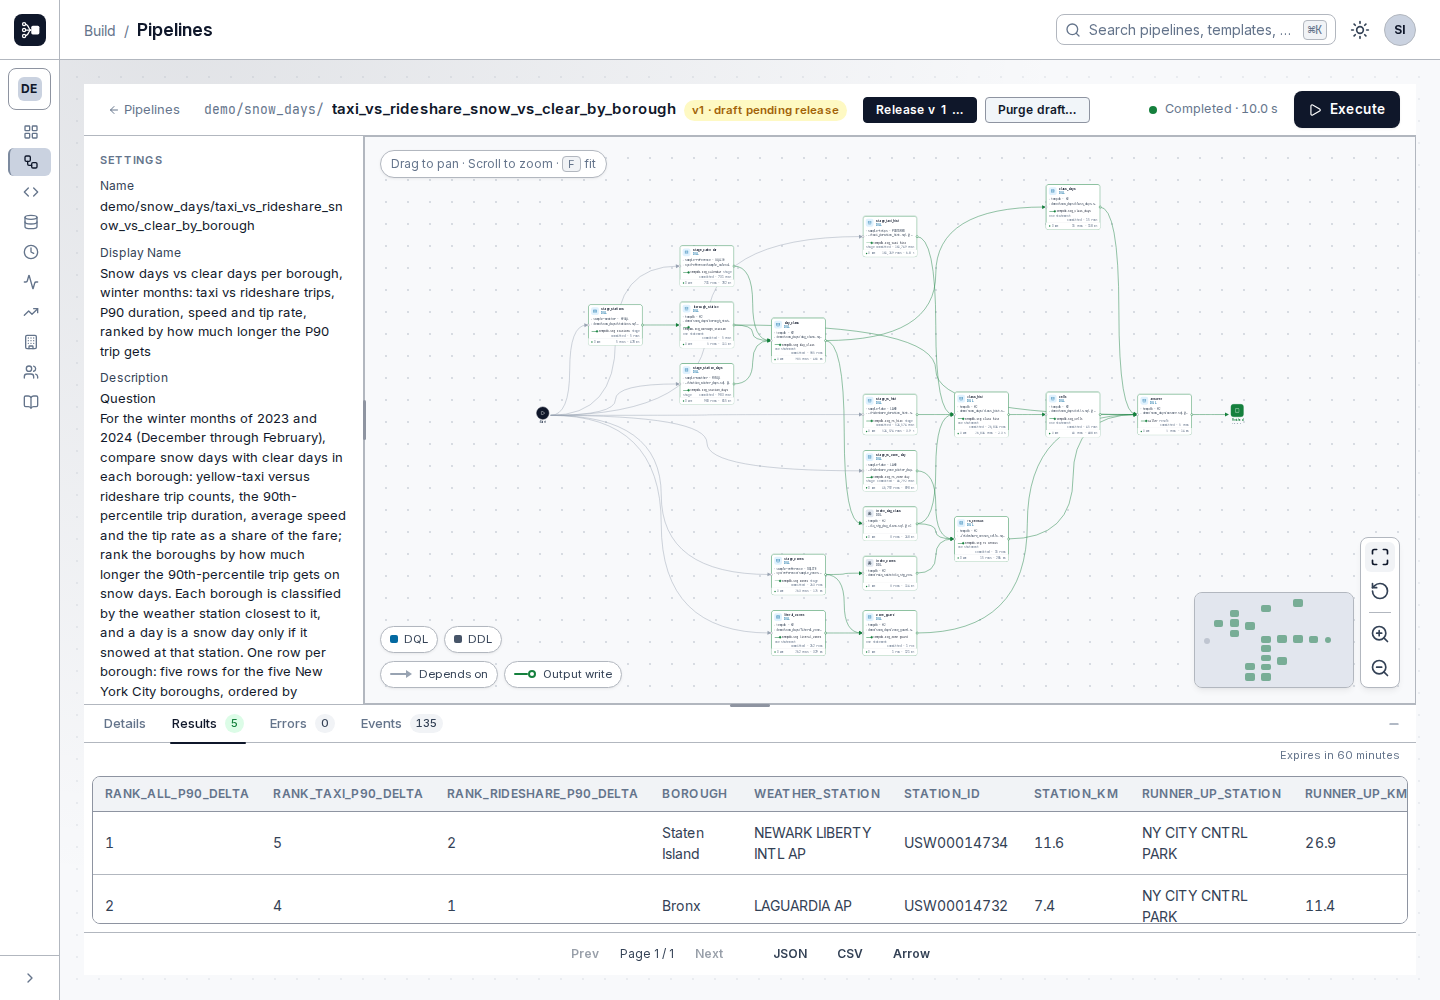
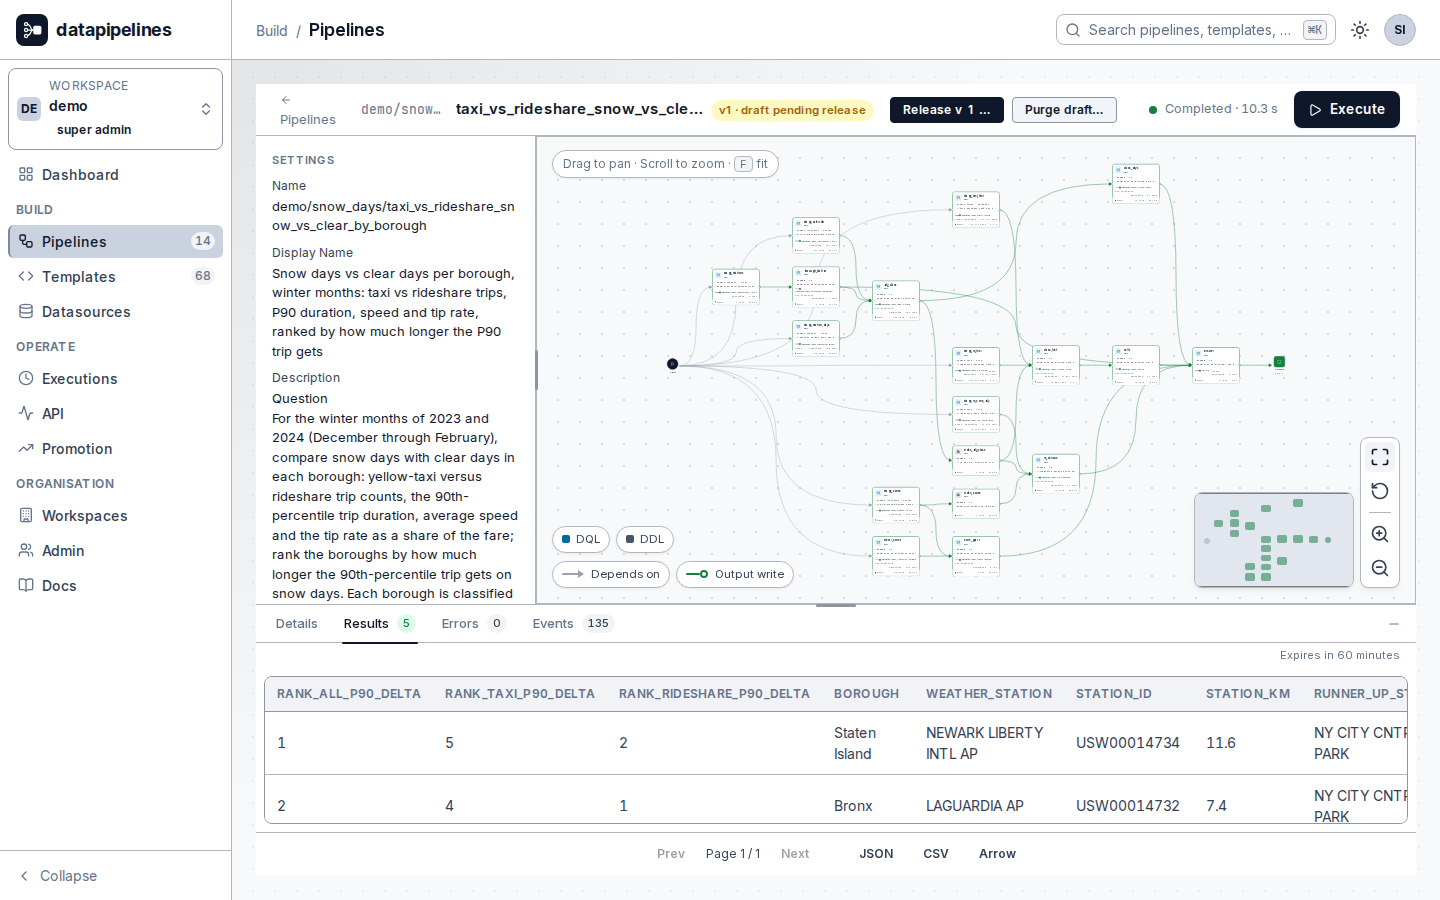
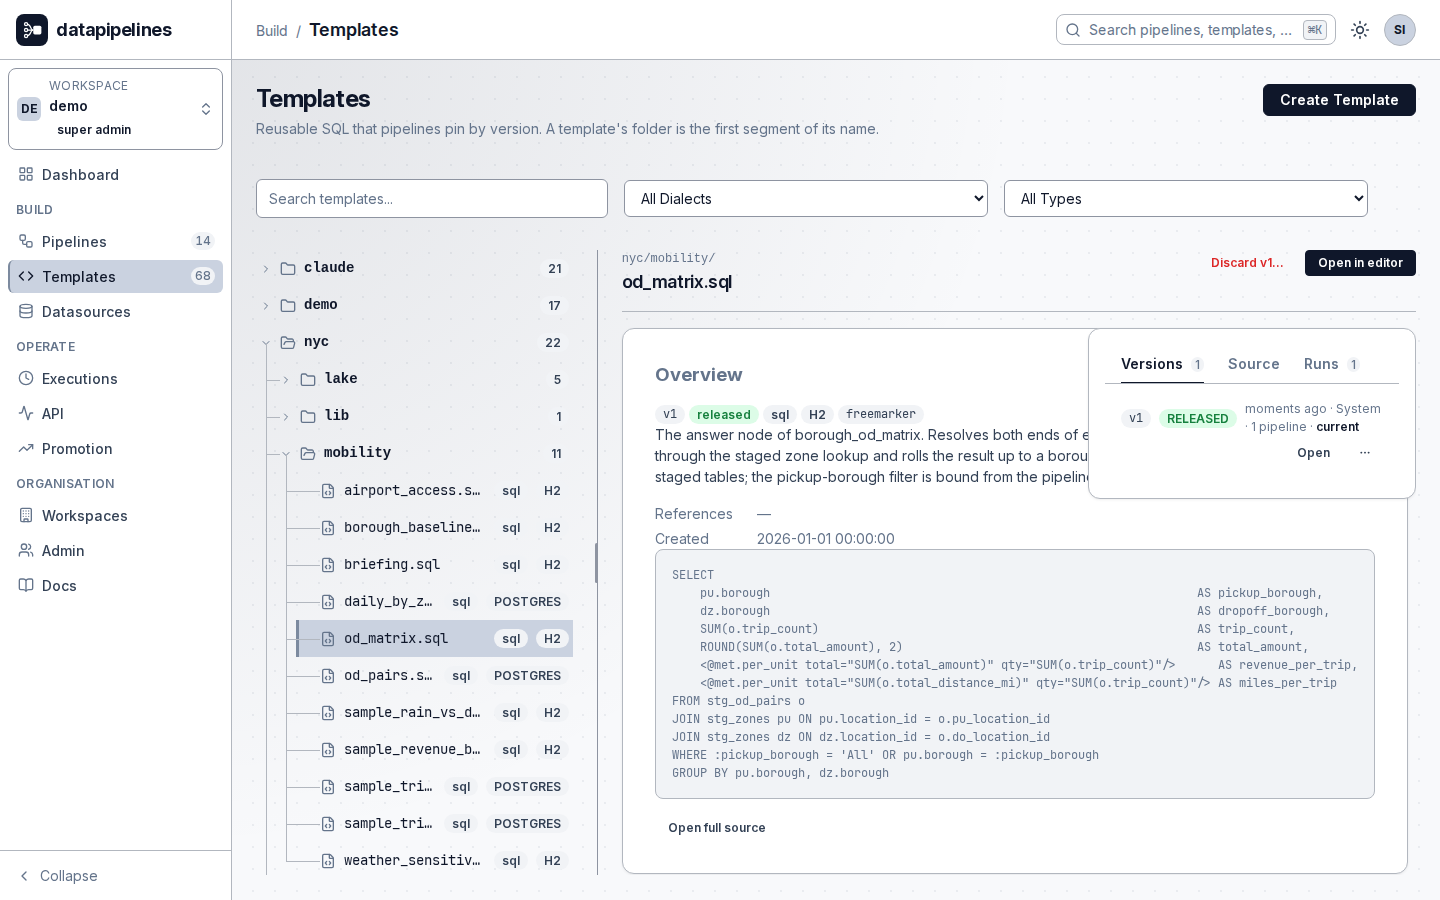
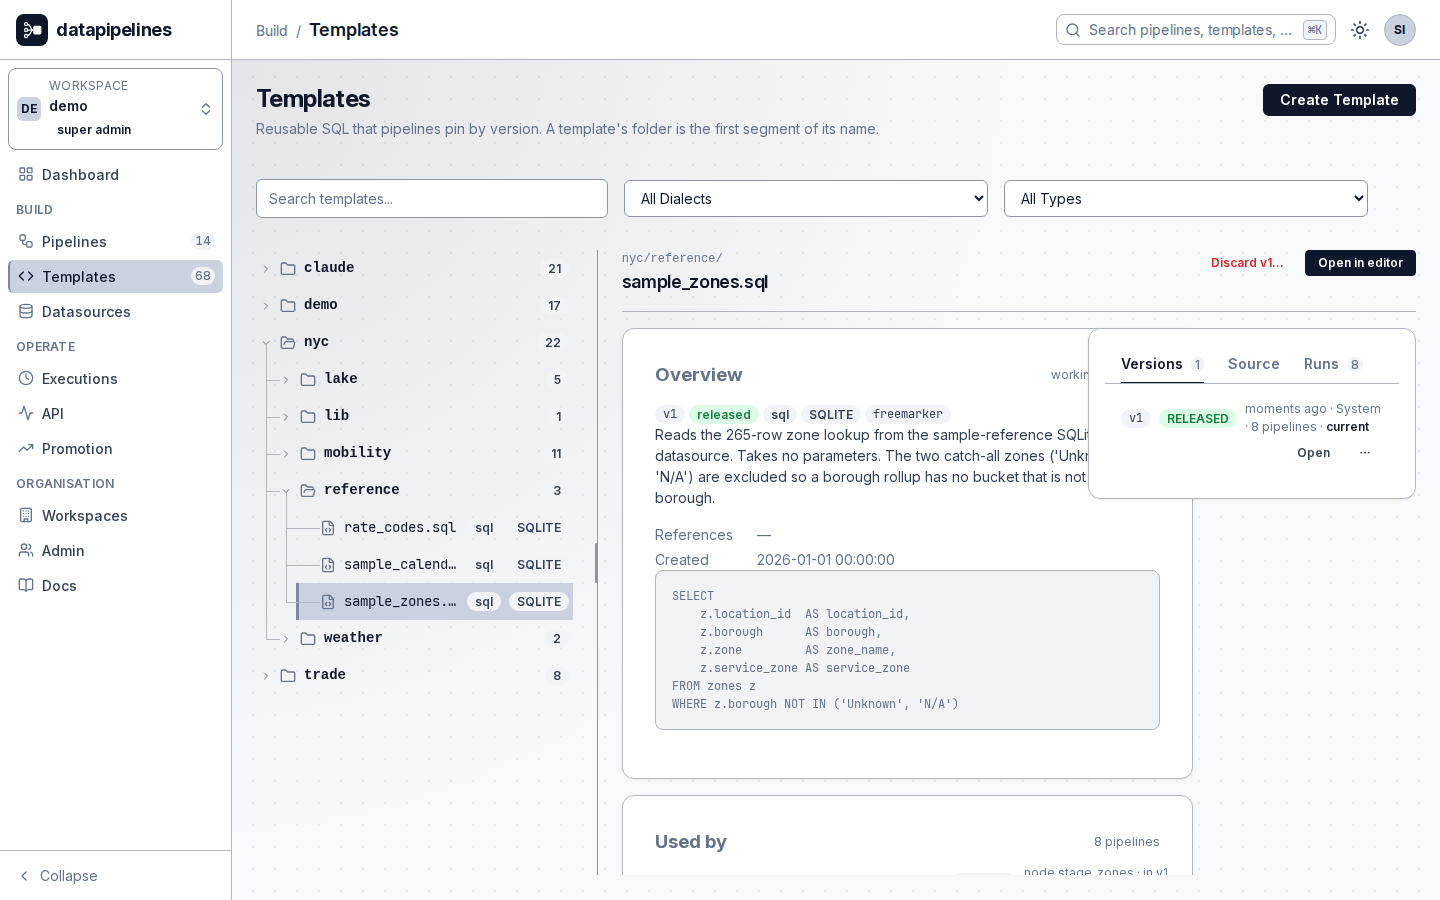
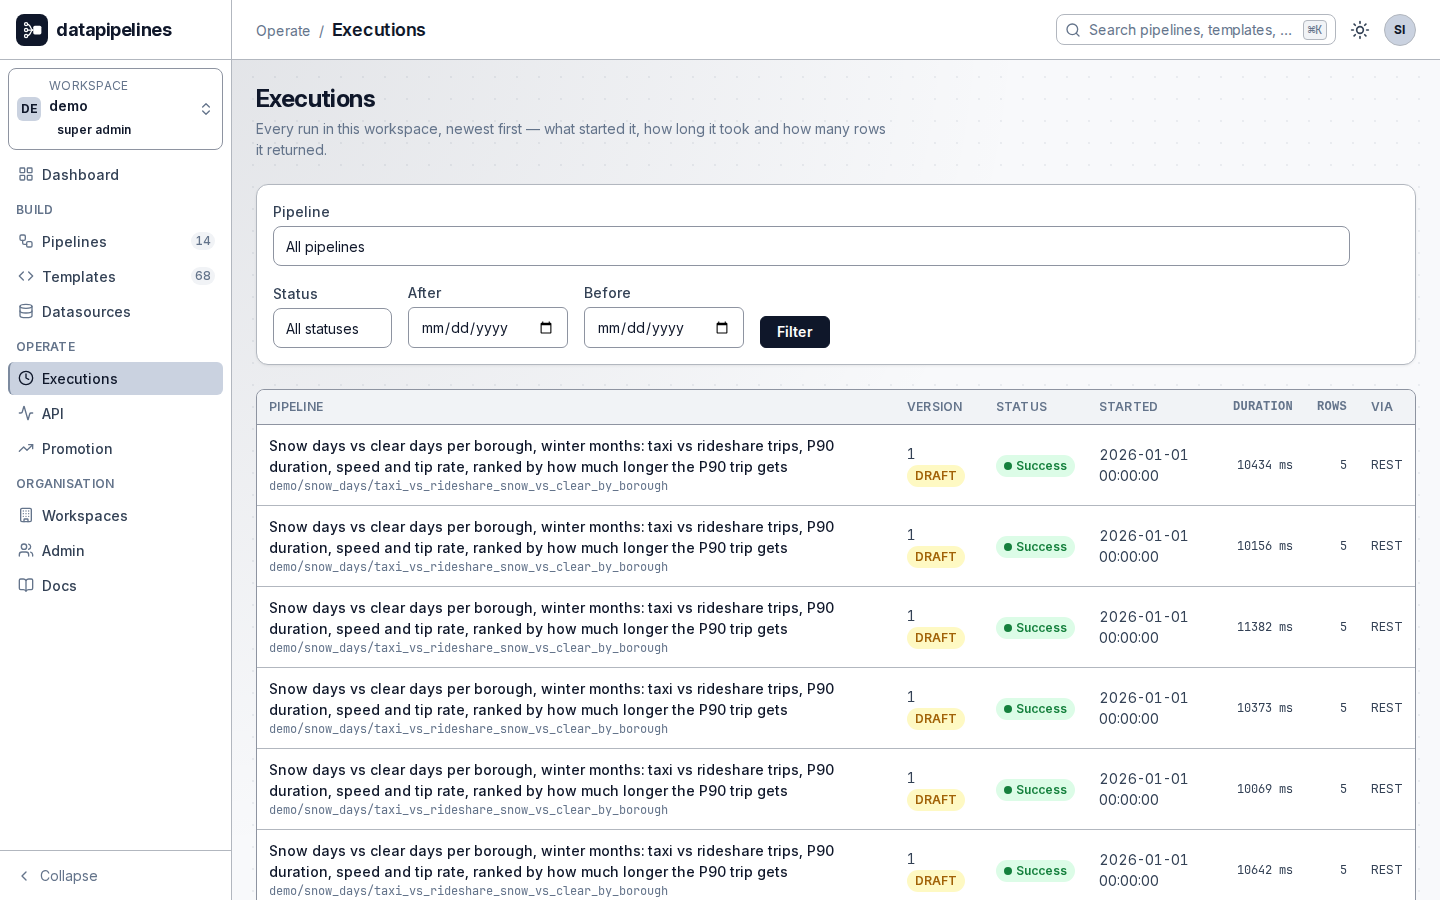
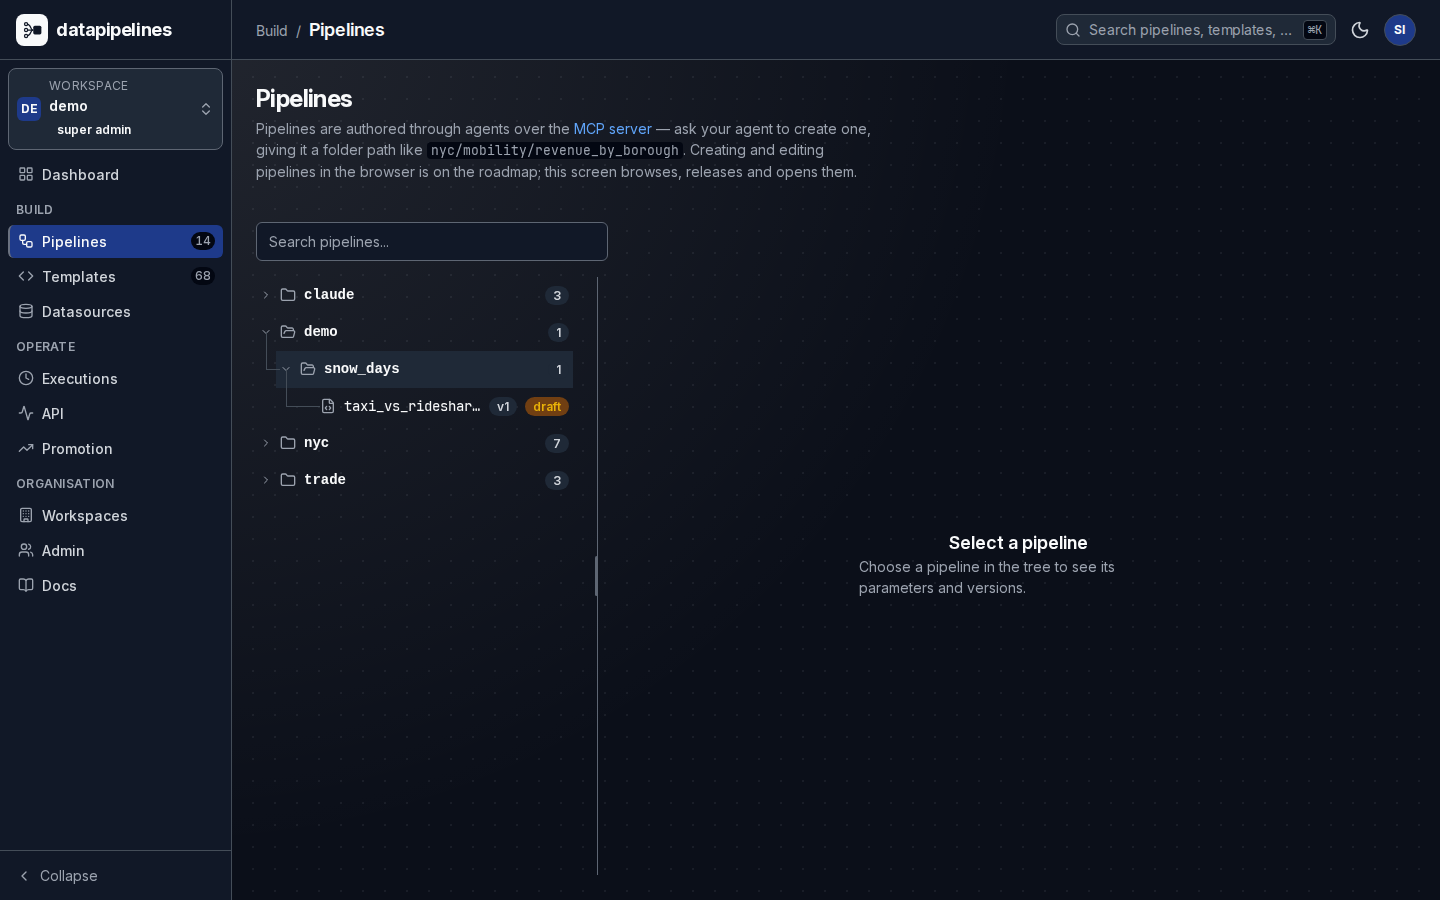
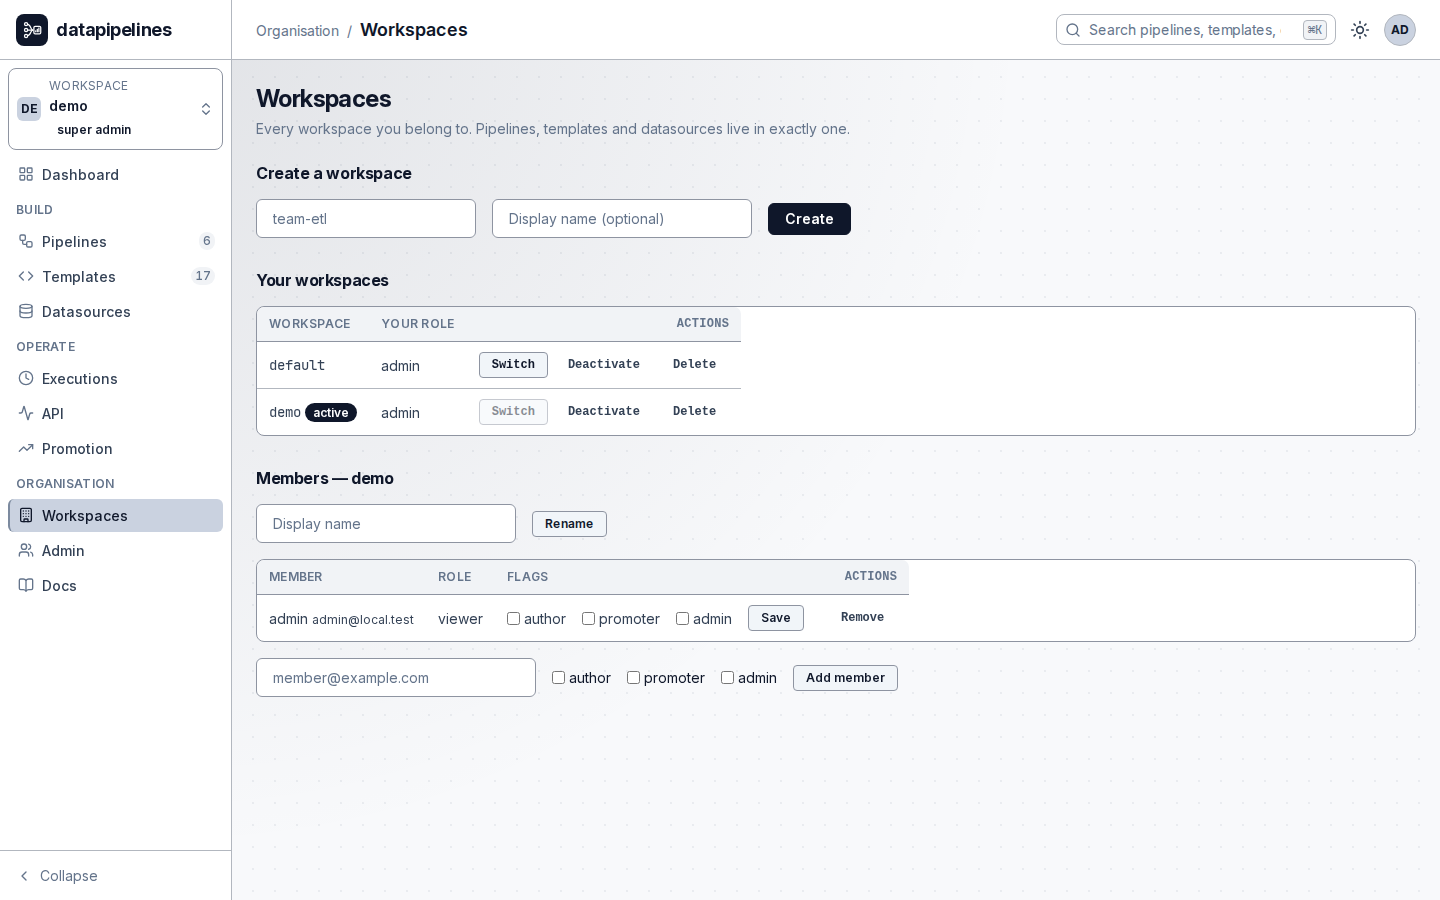
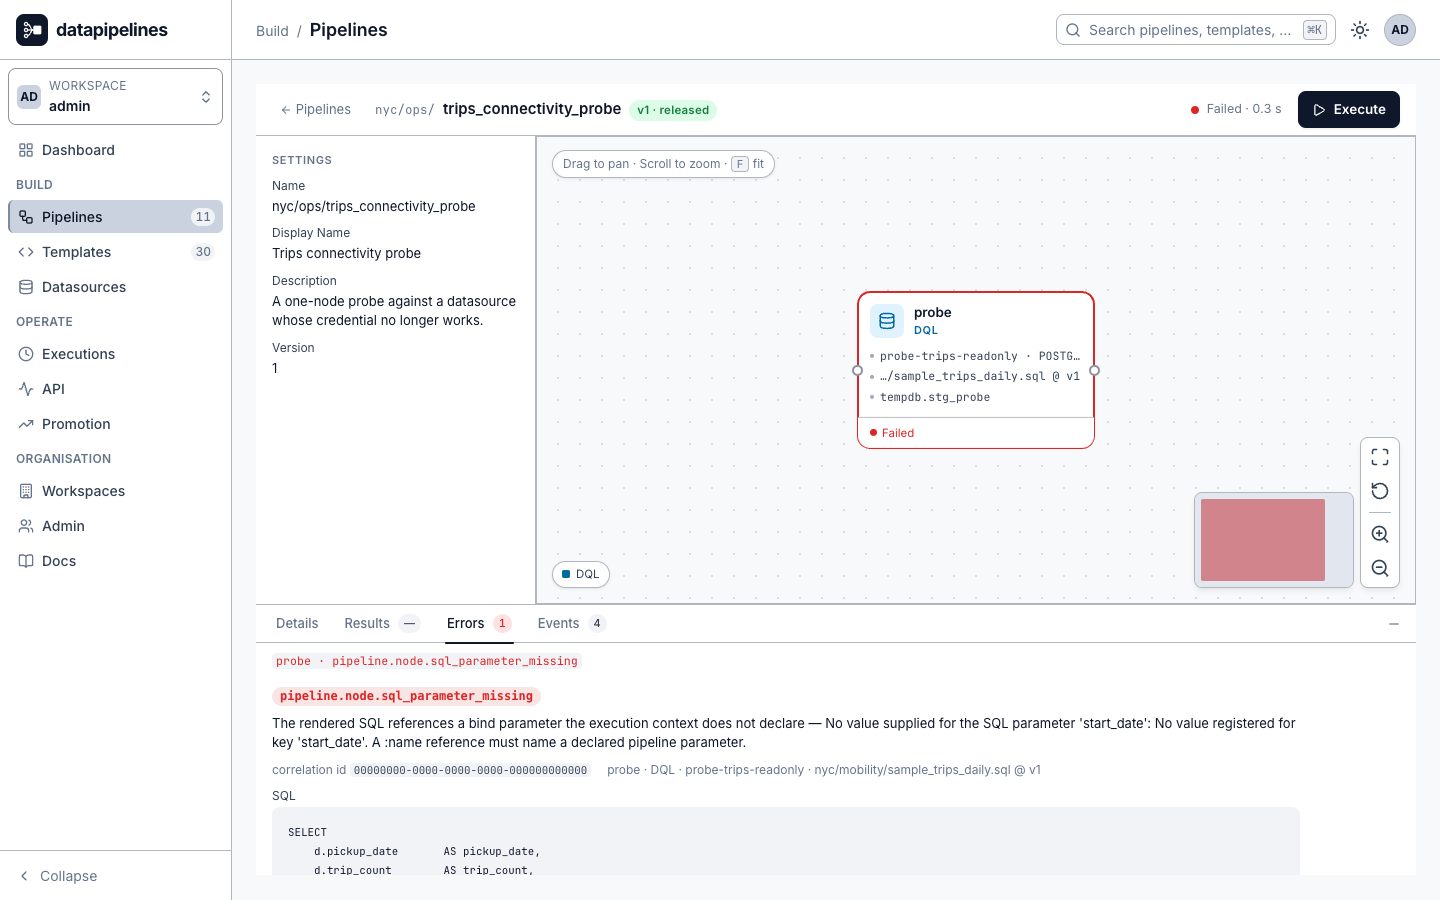
Real screens, photographed from a running demo deployment: the pipeline as it is built, the result as it is checked, and the release a person approves.
For the engineer who has to run it
The steps above ran the product. From here down is the mechanism behind them: what a dataset is here, where it runs, what the agent may and may not do, and what a release costs you. Every card below cites the spec section it comes from. View source and spot-check us.
A dataset here is a pipeline: a versioned JSON DAG of SQL nodes the agent authors over MCP against your real schemas. Each node runs on its own engine: Postgres, MySQL, SQL Server, Oracle, SQLite, DuckDB, or Parquet and Iceberg on S3 through dp-lake. Cross-engine joins happen in an in-memory staging database that exists only for the run. Nothing is copied to a warehouse; nothing lands. A release is immutable, and a released pipeline can be published as a GET endpoint.
One server, eight engines
Postgres, Oracle, SQL Server, MySQL, H2, DuckDB, SQLite and dp-lake, through one endpoint and one key per person. Each page has that engine's driver facts and a copy-paste client config.
Every dialect has its page. That includes H2, also the staging engine, and dp-lake, the LAKE dialect that reads Parquet and Iceberg on S3 in place. The dp-lake product page →
Shipped, not promised
Each card cites the spec section it comes from. View source and spot-check us. Caveats included where they exist. Honesty is the brand.
Pipelines are declarative JSON: schema_version, nodes, depends_on, parameters, settings. Every update creates a new immutable integer version, and the contract is additive-only.
A save-time scan walks the parsed template AST against a forbidden-construct list: ?eval, ?new, ?api, and in-body imports. SSTI vectors are rejected before a template is ever saved.
Declared parameters bind as :name on a prepared statement and are never interpolated. Interpolating one into the SQL text instead is refused at save with template.validation.parameter_interpolated.
Every template version is immutable. Body, imports, dialect and engine are frozen once stored, versions are never reused or renumbered, and each carries a content hash. Pipelines pin {name, version}, so a new template version is invisible to them until an author moves the pin.
Templates are typed: sql, which requires a dialect, or html, which has none and turns auto-escaping on. The type is fixed at creation and a database constraint enforces the pair.
A template's or pipeline's name is its path: nyc/mobility/revenue_by_borough, 2 to 10 segments. The first one is a folder, and the root holds folders only. A flat name is refused with details.reason = "folder_required".
An agent that invents a NEW top-level root is refused until it says so on purpose: confirm_new_root, with the roots that already exist in the error's details. Asking a person before creating a namespace is a guarantee here, not advice.
One draft per entity, at most. Releasing locks the version: we never modify a released pipeline. The next change copies it into a new draft. Discard drops the draft and returns the number to the pool.
The editor's version select is read-only for anything but the working version, and Edit reuses the existing draft or copies the selected version into a new one. The rule is visible on screen, not just enforced behind it.
The reverse arrow, answered as two different questions. Who uses this version now? scans every pipeline's working version and names the pipeline, the node id and the version carrying the pin. That is a fact you can go and change, not a count.
Is it safe to delete? scans every version ever, because historical versions stay executable. Delete is refused with 409 template.in_use while any pipeline version pins it.
Postgres, Oracle, SQL Server, MySQL, H2, DuckDB, SQLite and dp-lake. dp-lake is object storage read in place. One pipeline contract over all of them.
Oracle and MySQL drivers are opt-in for license reasons: pass -Poracle or -Pmysql, or drop the jar in lib/. A missing driver fails at save with datasource.driver_not_loaded. Everything else is in the published image, the DuckDB extensions included. A hardened deployment needs no egress to an extension repository.
A LAKE datasource queries Parquet and Apache Iceberg on S3 or any S3-compatible store with no warehouse and no load step. DuckDB is the engine; the catalog is the server's own registry, dp-catalog. Tables are registered over REST or by an agent through the lake_tables_* tools.
Hive-partitioned Parquet is scanned with partition pruning, so a date predicate reads the days it names and not the table. It is a read connector: there is no write path to the bucket. The whole dp-lake story →
Read the spec →Each execution gets its own isolated in-memory H2 tempdb, created at start and destroyed at end. Nodes stage ResultSets there, so downstream nodes join across engines.
A PIPELINE node executes a version-pinned child pipeline as a linked child execution, in-process, with lineage and family cancellation. The child keeps its own execution record, tempdb, stats and stream.
When SQL is the wrong tool, a SCRIPT node runs a versioned jsonata or javascript template over staged tables, in row, table or value mode. The engines have different capabilities and evaluation limits, with no network or filesystem access. JavaScript runs in the image's isolate, without Node.js or npm.
The DAG renders on a full-bleed canvas as node cards, with the facts inside the box: name, a type badge, datasource · dialect, template @ version, and after a run, elapsed time and rows.
One dock, four tabs: Details, Results, Errors and Events. A failure opens Errors, every event in arrival order.
It executes, streams, cancels and pages results. What it deliberately does not do is author: there is no edit mode in v1. Authoring is agent-first.
Read the spec →A failed node carries the catalogued code, the message, and the node's own facts: datasource, dialect, template @ version. It carries the rendered SQL in :name form, never a bound value, and the original exception chain with frames, root cause last.
The same record, built once, reaches the node_failed SSE event, the stored error_json, the editor's Errors tab and the agent's executions_get. No screen strips what another shows.
POST /api/v1/pipelines/{id}/execute returns text/event-stream with per-milestone events and heartbeats. There is no stream resumption. A dropped connection cancels the execution rather than orphaning it.
Cancel reaches the executing instance through Redis from any instance, and a per-node latch refuses to enter the driver once it has fired. A cancelled execution cannot come back SUCCESS. The window where it could was closed, and a test covers it by injecting the descheduling rather than racing it.
A schedule runs one pipeline at a five-field cron pattern's times in an IANA time zone, previews the next runs, and records every run. A run whose outcome is unknown blocks the schedule until a person looks. Run notices are available when scheduler mail is enabled and the schedule has recipients.
Pipeline scheduling →Visualizations and dashboards are versioned like pipelines: an agent drafts, a person releases. Configured actions refresh a dashboard's pinned sources on opening, from buttons or from bound filter controls. Its filters come from a reusable parameter set, and it embeds in your product through your backend, which keeps the key.
SQL dashboards →Push dev → staging → prod from the UI. The screen lists only released versions newer than the target's; drafts never leave the authoring environment, and templates and child pipelines travel first, as a dependency closure.
The credential is a server-kind API key, not a principal. It has no user account, so rotation and offboarding are independent of any person. To rotate: create a second key, set it on the sender, revoke the first. Neither side restarts.
Instances are symmetric and stateless for API, MCP, UI and auth. There are no sticky sessions. Only a running execution is pinned to one JVM; cancel works from any instance through Redis, and results and history are readable from all of them.
Datasource pool invalidation rides a Redis channel: repoint or rotate a credential on one instance and every other evicts its pool and rebuilds from the row.
A crashed instance's in-flight executions are swept to ABORTED by an idempotent stale-execution sweep every replica runs.
Everything a program uses to talk to a workspace, on one screen: the endpoints you have published as GET /api/…, the keys that may call them, and the MCP connection block. The tool count is rendered live from the catalog, never a literal.
It is honest about what it cannot show. There is no "calls in the last 24 h" column: every serve is audited, but nothing tallies them per endpoint. The card states the absence instead of filling it from a sample.
Read the spec →Eight HikariCP settings are on the datasource form, each prefilled with its effective default and labelled with where that default came from. A field left alone is not persisted, so a later change to a product default still reaches the datasource.
Out-of-range values are refused, not accepted. Every floor restates a rewrite Hikari would otherwise perform silently, and the test that justifies them builds a real pool and watches it happen.
Read the spec →Editing or deleting a datasource retires its pool instead of closing it: new leases build a fresh pool from the new row at once, idle connections close now, and a connection still in use closes when its borrower returns it, never mid-statement.
Delete asks the question first: the dialog runs the any-version usage scan before it offers anything, and lists pipeline › node (v3 released) for every reference. The 409 and the dialog cannot disagree. It is the same scan.
Logins, key lifecycle, permission denials, user admin, workspace events, promotion accept/reject, every MCP tool call and each credential-decryption point, recorded with actor, cause and source IP.
Failures arrive as stable {domain}.{entity}.{failure} codes in a uniform error envelope. It is a catalog enforced against the code by drift tests, and the same codes flow over MCP. Agents get errors they can branch on, not prose to parse.
you › Which rideshare company carried the most trips in each borough last quarter?
| borough | top company | trips | borough trips | share |
|---|---|---|---|---|
| Manhattan | Uber | 17,660,839 | 23,669,163 | 74.62% |
| Brooklyn | Uber | 11,946,362 | 16,057,699 | 74.40% |
| Queens | Uber | 9,786,602 | 12,847,231 | 76.18% |
| Bronx | Uber | 6,078,750 | 7,572,899 | 80.27% |
| Staten Island | Uber | 715,593 | 918,360 | 77.92% |
GET /api/demo/v1/top-company-by-borough?anchor_date=2025-01-01 · after release · key scoped to /demo
from the demo workspace. A real result, not a promise
| endpoint | serves | key reach |
|---|---|---|
GET /api/demo/v1/top-company-by-borough?anchor_date=2025-01-01 |
demo/top_company_by_borough · v1 | /demo/** |
from the demo workspace. Released by a human, served as this version forever
Every request resolves exactly one workspace; all authored content is workspace-scoped; API keys are pinned to one workspace. Membership comes in five roles: viewer, author, promoter, workspace admin and super admin.
The management UI ships: create, switch, manage members, a navbar switcher and add-by-email.
Four kinds. mcp: the agent's own identity, with the role its creator chose; it reaches only /mcp. endpoint: the api caller role, limited to bound published paths. server: promotion routes. dashboard: one external app's embeds.
A central check confines each kind before the handler's permission check. A new route never expands another kind's reach.
Read the spec →There is deliberately no tool that registers a datasource, and none that creates a key: a credential through a tool call would land in the agent's context and transcript. A person adds the datasource in the UI; the agent uses it by name.
What the agent keeps is everything that needs no secret: list, get, test, schemas, tables, columns and preview rows. Enough to author without a password.
Read the spec →Humans sign in through OIDC SSO. An agent's key is an identity of its own, holding the role its creator chose for it. A program's API key is an identity too. Separate principals, separate blast radii.
No identity provider? Turn on local accounts and the whole product runs with zero external setup. Hashes are Argon2id through the same hasher API keys use. There is no self-registration: an admin creates the account, or config seeds the first admin only.
Every seeded or admin-reset credential is one-time and the app refuses every other screen until it is changed. Five consecutive failures lock the account. The unknown-email path spends the same hashing memory, so timing cannot enumerate it.
Read the spec →is_readonly forbids write-shaped uses. It is enforced at save time, at an executor backstop, and as Hikari readOnly. Admins turn it on for global datasources. The flag is a contract, not containment. Pair it with a SELECT-only DB user.
Passwords are AES-256-GCM encrypted with the row's name bound as additional authenticated data, so a ciphertext moved between rows fails to decrypt. The app refuses to start without a valid key.
Every credential carries a key version, and datapipelines.db.key-provider selects where the key comes from. One contract test covers every provider.
Scheduling, dashboards and parameter sets each have a page: pipeline scheduling, SQL dashboards and parameter sets. What is not built yet is on the roadmap.
Your infra, your rules
Runs on your hardware, under your policies. The defaults are paranoid so you don't have to be.
DATAPIPELINES_ENV, and how careful the product should be with DATAPIPELINES_POSTURE: development or hardened. Configuration lives in exactly two files. A tracked deploy/env/defaults.env carries every non-secret default. A git-ignored deploy/secrets.env holds the secrets, and ./app.sh --scaffold writes it for you with every secret generated. The hardened setting refuses the demo at boot.
429 rate_limit.unavailable rather than waved through. A limiter that opens under its own outage is not a limit.
Before you begin, and once you run it
Yes. Someone deploys the server on your infrastructure (docs/deployment.md §4), registers the database connections in the application, because there is deliberately no agent tool that registers one (docs/mcp-server.md §6.2.22), and connects the AI client. After setup, business questions can be asked in plain language; a person who understands your data reviews the resulting SQL and numbers.
The server holds your database credentials and the agent never sees them (docs/datasources.md §7), but the schema, statistics, preview rows and execution results the agent asks for are returned to it (docs/mcp-server.md §6.2.15), and so may reach the model provider behind your client. Choose the client, the model and the datasources' access to match your requirements.
Not yet. Today authoring is through an AI agent over MCP or the REST API; the browser helps you inspect a pipeline, execute it, read results and errors, and manage draft and released versions (docs/pipeline-editor.md §11). Browser authoring is a roadmap item (docs/ROADMAP.md §2).
A released pipeline gets a URL of its own, /api/<your-namespace>/<version>/<path>; a GET runs it with the query string bound to its declared parameters and returns the rows as JSON. Keys are bound to a path prefix, so a partner can be given one endpoint and nothing else. The serving contract is docs/rest-api.md §19.
For the API half, today: an agent authors the pipeline against your databases, runs it, fixes what fails, you review and release, and the endpoint exists. No deployment, no service to write, no gateway to configure. The same released pipeline can also feed a dashboard your agent drafts and a person releases, embedded in your product through your own backend (docs/dashboards.md §6.5). Publishing is docs/rest-api.md §19.
One Docker image beside a PostgreSQL metadata database and Redis. ./app.sh --start --demo nyc builds the image, downloads the published sample data and brings the stack up; the reference compose file and the demo quickstart are docs/deployment.md Appendix A and Appendix B.
Every statement carries a query timeout and the run an overall deadline; a node that outlives its budget fails with pipeline.node.query_timeout and the elapsed time, and the SQL probe returns the plan, so the agent fixes the shape instead of guessing. The limits and cancellation are docs/dag-executor.md §5.
Not today. It sits beside them: it can feed Tableau a governed dataset through an API or a datasource table Tableau connects to, and it replaces the warehouse-plus-dbt step for teams that never wanted one (docs/pipeline-contract.md §8). It has SQL dashboards over released pipelines (docs/dashboards.md §1) and schedules that run pipelines (docs/scheduler.md §1), without a BI tool's drag-and-drop authoring; alerts are not built. The draft and release lifecycle is docs/versioning.md §3.
Where to next
The tutorial ended with a governed API over a reviewed pipeline. The three directions it opens:
Mid-session the agent recorded the rainy-day rule as a workspace definition. The next session, and the next agent, starts with it instead of re-deriving it. The semantic layer →
The checks the release dialog ran are declared on the pipeline: counts, totals, invariants. They run again at every release. The specs →
Run the released pipeline on a schedule, or chart it on a dashboard. Report delivery and alerts are not built yet. See the roadmap →
Explore the sample data first. Connect your own databases when you’re ready.